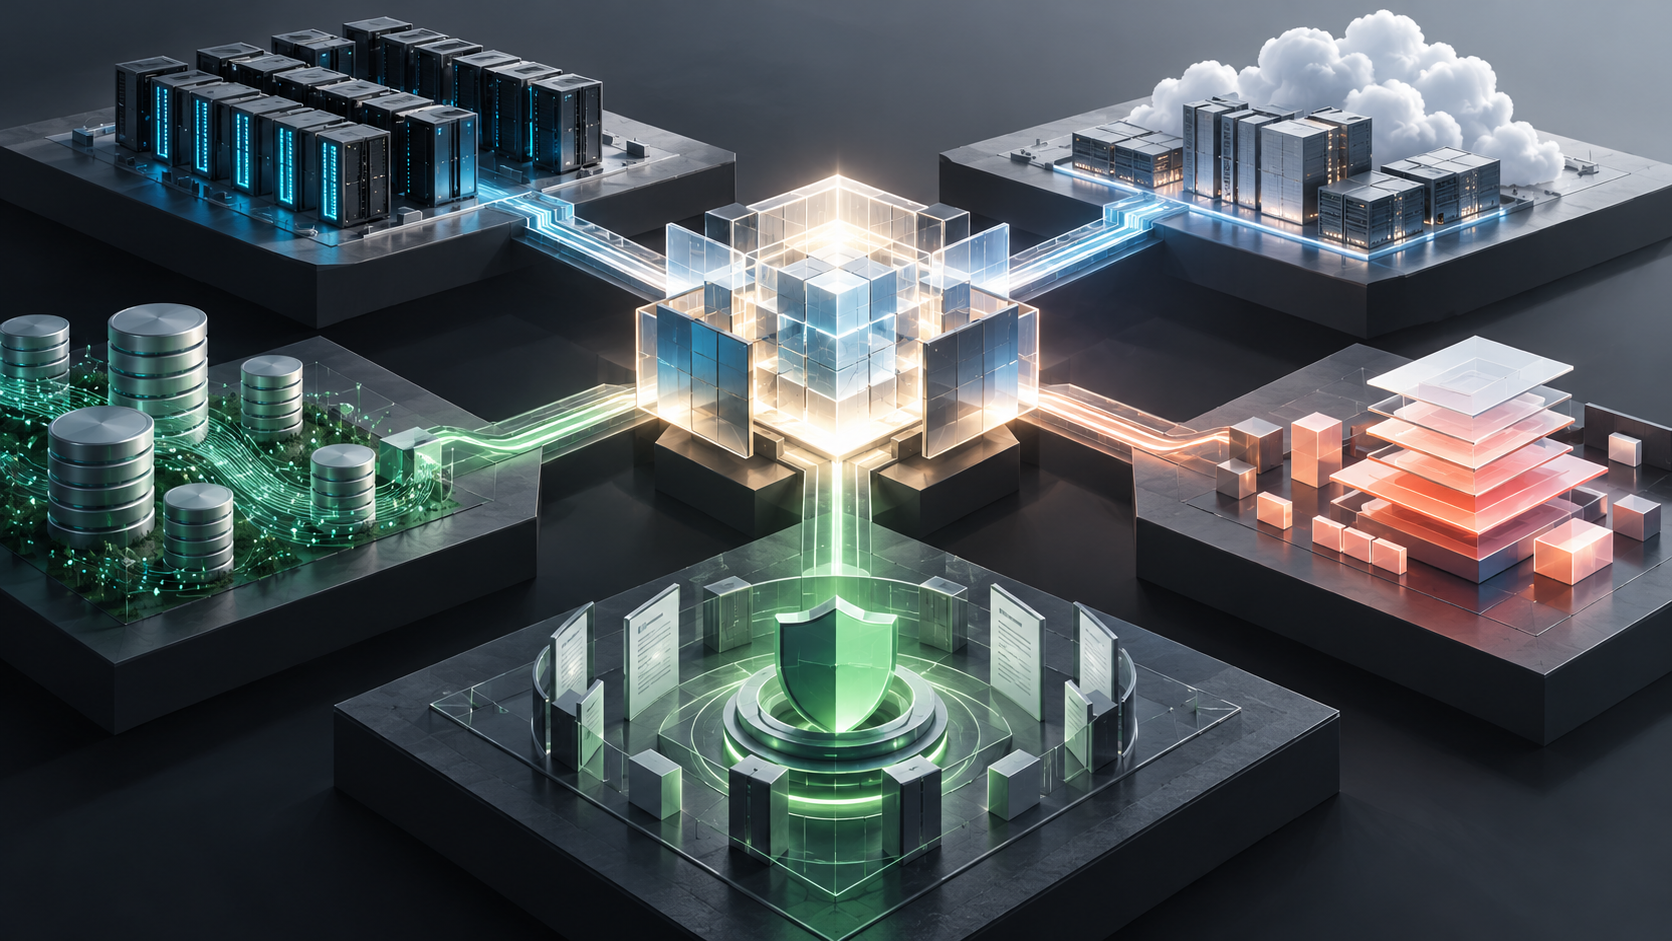
Open weights are widening enterprise choice, but the most important competitive shift is happening around the model: in compute, inference, data, workflows, evaluation and governance.
A model file can now arrive with the air of a strategic breakthrough. Download the weights, point them at an inference stack, and an enterprise appears to have escaped the economics and control of a proprietary API.
That story is attractive because it contains an important truth. Access to capable model weights has expanded dramatically. The release wave from Llama, DeepSeek, Qwen, gpt-oss and OLMo has made it plausible for far more organisations to run, adapt and distribute models outside a single vendor’s hosted service. Public benchmarks also show that the gap between some open-weight and closed models has narrowed on several tasks.
But the model file is not the revolution. It is the point at which the AI stack begins to come apart.
Once model access is separated from a single provider’s service, the enterprise has more choices. It also has more decisions to make. Who supplies the compute? Which runtime serves the model? What does the licence permit? Which data can be used for adaptation? How will quality be evaluated? Who patches vulnerabilities, handles incidents and proves compliance? How difficult is it to replace the model without rebuilding the application around it?
Open models are changing competition less by making intelligence free than by unbundling the layers through which intelligence becomes a reliable product or business process. That weakens some forms of market power, creates others, and moves the practical source of differentiation towards infrastructure, data, workflow integration, evaluation, distribution and governance.
For enterprise leaders, the useful question is therefore not, “Should we choose open or closed AI?” It is, “Which parts of the stack should we control for this workload, and what capabilities are required to make that control real?”
Stop calling everything open source
The first obstacle is language. “Open model” is often used as if it described a single, well-understood category. It does not.
The Open Source AI Definition 1.0 from the Open Source Initiative, or OSI, sets a demanding threshold. An open-source AI system must grant freedoms to use, study, modify and share the system. Exercising those freedoms requires more than weights. The preferred form for modification includes the model parameters, the code used to train and run the system, and sufficiently detailed information about the training data.
That definition is valuable because it exposes what the label “open” can conceal. At least five dimensions matter:
- Access: Are the weights available, or only an API?
- Rights: Can the artefacts be used, modified and redistributed for the intended purpose?
- Code: Are inference code, training code and data-processing code available?
- Data information: Is there enough information to understand and reproduce the training process using the same or similar data?
- Training artefacts: Are recipes, checkpoints, evaluation materials and other intermediate components available?
These dimensions produce a spectrum of practical openness, even though the OSI definition itself is a threshold for using the specific term “open source”.
At one end is a closed service. Users can submit prompts and receive outputs, but the weights and training process remain inaccessible. A step further along, a provider may publish interfaces, model cards or selected technical details without releasing the weights. Open-weight releases make the learned parameters available, but their licences and disclosures vary. Some use broadly permissive terms, while others add restrictions or omit much of the training process. At the furthest end are fully open research systems that publish weights, code, data information, recipes, evaluations and intermediate artefacts.

This distinction is not pedantic. It changes what an enterprise can build, redistribute, audit and depend on.
Meta’s Llama models, for example, are widely described as open. The weights are available under Meta’s community terms, but the OSI argues that restrictions in the licence prevent Llama from meeting its open-source criteria. Qwen3 and gpt-oss released weights under Apache 2.0. DeepSeek releases use permissive terms for important artefacts, with additional care required around the lineage and licences of distilled models. OLMo was designed as a fully open research system, publishing far more of the training and evaluation process.
None of these facts, by itself, says which model is best for a workload. They say that “open” is not a procurement specification. A serious evaluation records the exact checkpoint, the exact licence version, the disclosed artefacts, the model’s provenance and the operational conditions attached to its use.
Five releases, five different bargains
The recent open-model wave matters because it expanded the design space in kind, not simply in quantity.
Meta’s July 2024 Llama 3.1 release put a 405-billion-parameter model with a 128,000-token context window into a broadly available weight-release ecosystem. Its strategic effect was not only technical. It reinforced a large downstream community of fine-tuning, quantisation, tooling and managed deployment around a model family that sits outside an ordinary open-source licence.
DeepSeek then showed how architecture and training economics could become part of the competitive story. The DeepSeek V3 repository documents a mixture-of-experts model with 671 billion total parameters but 37 billion activated for each token. DeepSeek reports 14.8 trillion pre-training tokens, 2.664 million H800 GPU-hours for pre-training and 2.788 million for full training. Those are provider-reported facts, not a complete commercial cost comparison. Their more durable lesson is that headline parameter count does not map directly to inference work, and that system architecture matters to both capability and economics.
DeepSeek R1 added a reasoning-focused release and permissive terms for its released materials, while illustrating a second complication: downstream models can inherit conditions from their base models. The family name alone is never enough for legal or technical diligence.
In April 2025, Qwen3 widened the choice further. Its flagship mixture-of-experts model has 235 billion total parameters and 22 billion active parameters, alongside a range of dense and smaller sparse models. The released weights use Apache 2.0. The range matters as much as the flagship because it lets organisations explore different quality, latency and hardware profiles without treating one enormous checkpoint as the default answer.
OpenAI’s gpt-oss model card documented 120b and 20b open-weight reasoning models under Apache 2.0 in August 2025. The release combined permissive model access with a provider usage policy and explicit safety analysis. It is a useful reminder that licence freedom, responsible-use expectations and deployment responsibility are related but distinct questions.
OLMo 2 offers a different bargain. The Allen Institute for AI describes it as a fully open family developed with accessible training data, open-source training code, reproducible recipes, transparent evaluations and intermediate checkpoints. For researchers, auditors and organisations that need to inspect provenance, those additional artefacts can be more valuable than a marginal benchmark advantage. They enable questions that cannot be answered from weights alone.
These releases do not form a ladder with one winner at the top. They form a menu. Enterprises can trade among capability, size, licence, disclosure, hardware needs, ecosystem maturity and operational control. That is the structural change: model selection has become a portfolio problem.
The capability gap narrowed, unevenly
An expanded menu would mean little if open-weight models remained far behind on every useful task. They do not.
The Stanford AI Index 2025 reported that the gap between selected closed and open-weight models on Chatbot Arena narrowed from 8.0 per cent in January 2024 to 1.7 per cent by February 2025. On MMLU, the report said a 15.9 percentage-point gap in late 2023 had shrunk to 0.1 percentage point by the end of 2024.
Those figures deserve attention. They show how quickly public capability comparisons changed. They do not establish universal parity.
A benchmark score is the output of a measurement system. The result depends on the task set, prompt, sampling settings, reasoning budget, tool access, model version and scoring rule. Provider tables often differ across several of those dimensions. A repeated-sample metric can answer a different question from single-attempt reliability. A coding benchmark may reveal little about multilingual document classification, a regulated decision-support process or a tool-using workflow with expensive failure modes.
Independent suites such as HELM Capabilities improve transparency by standardising scenarios and exposing prompt-level results. Dynamic benchmarks such as LiveBench try to reduce contamination by changing questions. Neither turns a public leaderboard into a substitute for production evaluation.
The correct conclusion is narrower and more useful: open-weight models are credible candidates for more workloads than they were before. That expands negotiating leverage and architecture choice. It does not end model selection.
For an enterprise, the relevant evaluation should reproduce the work that matters. It should include the organisation’s language mix, document types, retrieval method, tool schemas, safety constraints, latency target and cost of failure. It should measure the complete system, not only the base model in isolation. A modest model with strong retrieval, validation and workflow boundaries can outperform a more capable model inside a poorly engineered process. The reverse is also true.
Benchmark progress changes the option set. System performance determines the business choice.
The enterprise bargain: control in exchange for capability
Open weights offer four frequently cited advantages: customisation, data control, lower latency and reduced vendor dependence. Each can be real. None arrives automatically.
Customisation is a system, not a fine-tune
Access to weights lets teams adapt a model, quantise it, optimise inference and run it inside a chosen boundary. Techniques such as low-rank adaptation, or LoRA, can reduce the amount of trainable state required for specialisation. The original LoRA paper reported 10,000 times fewer trainable parameters and roughly three times lower GPU memory than full fine-tuning of GPT-3 in its tested settings.
That is an important technical mechanism, not a current enterprise TCO guarantee. Adaptation still requires representative data, evaluation, lineage controls and a deployment process. A fine-tuned model can regress on general capabilities, encode poor examples or create a maintenance burden when the base model changes. The asset is not merely the adapter. It is the repeatable process that proves whether the adapted system remains fit for purpose.
Data control is architectural
Self-hosting can keep prompts, retrieved context and outputs within an organisation’s selected boundary. That can be valuable for sensitive workflows, residency constraints or predictable latency. Yet the boundary must include more than the model server. Logs, telemetry, vector stores, fine-tuning data, support channels and incident workflows can all reintroduce external dependencies or data exposure.
A managed endpoint may offer stronger practical controls than a nominally self-hosted system if the organisation lacks secure serving, patching and monitoring. Conversely, a mature platform team may gain meaningful control by operating the model directly. The right answer depends on actual operating capability, not the label attached to the weights.
Zero-price weights do not create zero-cost inference
The acquisition price of a weight file is only one line in the cost model. Dedicated accelerators, utilisation, energy, storage, networking, reliability, specialist staff, evaluation, safety testing and lifecycle maintenance all matter.
Serving software can change that equation materially. The PagedAttention paper reported two to four times higher throughput than its tested serving baselines at similar latency. Quantisation can reduce memory requirements and improve performance, with quality effects that depend on the model, method and hardware. Batching and traffic shape determine whether expensive accelerators stay busy.
This creates two opposite but equally plausible outcomes. At sustained scale, an optimised, well-utilised deployment can be economically attractive compared with token-priced APIs. At low or volatile utilisation, a dedicated cluster can become expensive idle capacity, while a managed service converts infrastructure into variable cost.
Any universal claim that open models are cheaper is therefore suspect. A defensible comparison specifies traffic volume, concurrency, latency, context length, output length, availability, hardware, utilisation, staffing and evaluation overhead. It also values the option to switch, even if that option is not exercised immediately.
Portability must be rehearsed
Open weights reduce one form of lock-in because an organisation can, in principle, take the model to another runtime or environment. Applications still bind to tokenisers, prompt behaviour, tool schemas, context handling, safety filters, fine-tunes and evaluation thresholds. Managed catalogues make it easy to select among models while potentially deepening dependence on the platform that serves them.
True optionality is demonstrated through replacement tests. Can the organisation swap a model while preserving a stable application interface? Does it have a common evaluation suite that exposes regressions? Are prompts, policies and tool contracts versioned outside the provider’s proprietary layer? Can it move an adapted model, or only the unmodified base weights? What happens to observability and incident response after a switch?
If those questions have not been tested, open weights provide theoretical portability, not an exit plan.
Governance responsibility follows the deployment
An open licence does not remove the need to assess risk, protect data, document decisions, test performance or respond to incidents. More control can mean more responsibility.
The EU AI Act illustrates the need for precise qualification. Under Article 53(2), providers of qualifying free and open-source general-purpose AI models may be exempt from the technical-documentation duties in Article 53(1)(a) and (b). The copyright-policy and public training-content-summary duties in Article 53(1)(c) and (d) continue to apply, and the exemption does not cover general-purpose AI models with systemic risk. Obligations also depend on the organisation’s role and the dates on which provisions apply. European Commission guidance should be read alongside the legislation and current implementing measures; this article is not legal advice, and the rules should not be reduced to “open source is exempt”.
In financial services, the deployment question becomes even more concrete. A bank that self-hosts an open-weight model may reduce external data transfer while taking on more direct responsibility for validation, resilience, change management and third-party infrastructure. A hosted proprietary model may simplify some operations while introducing concentration, contractual and exit risks. Neither licence category supplies the control framework.
Where value moves when weights are accessible
If competent model weights become more available and substitutable, some economic value can move away from exclusive access to the base model. It does not disappear. It moves towards scarce complements.
The first is compute. Advanced chips, data-centre capacity and energy remain concentrated and capital intensive. An open-weight ecosystem can increase demand for those inputs. Cloud providers can benefit from broader model choice because every deployment still consumes infrastructure.
The second is inference. Runtime engineering determines how efficiently a model uses hardware, how it batches requests, manages memory and meets latency targets. Enterprise packaging adds authentication, autoscaling, monitoring, patching, policy enforcement and support. A permissively licensed model can therefore sit inside a highly commercial delivery layer.
The third is the platform. Managed catalogues let enterprises compare and deploy multiple models without building every serving capability themselves. That reduces operational friction but can relocate lock-in from the model to the control plane, identity system, evaluation tooling or data services.
The fourth is proprietary context and workflow integration. A base model becomes useful when it can access the right information, operate within permissions, invoke reliable tools, and return outputs into a business process. The data model, feedback loop, process design and distribution channel can remain defensible even when two competitors can download similar weights.
The fifth is evaluation and governance. As model supply expands, the ability to compare models continuously becomes valuable. Enterprises need tests that reflect actual work, thresholds tied to risk, evidence for change approval, and monitoring for drift or new failure modes. That capability is difficult to buy as a static product because it encodes the organisation’s own standards and processes.
This is why “commoditisation” is too blunt. Accessible weights can increase price pressure and reduce switching barriers at the base layer while increasing the importance of everything around it. Frontier providers may still differentiate through research speed, integrated tools, multimodal capability, trust, distribution and operational simplicity. Open-model providers may build strong businesses through support, hosting or ecosystems. Application companies may capture value through domain execution.
The likely outcome is not the disappearance of the model layer. It is a more modular contest over where control, scarcity and customer value reside.
How the competitive map changes
Unbundling changes competition through several mechanisms at once. They do not all point towards a less concentrated market.
Entry becomes easier at one layer
Access to capable weights lowers the cost of experimentation for software companies, researchers and internal product teams. A team can test an idea without negotiating access to a single frontier API, and it can adapt a model to a domain or language that a general-purpose provider may not prioritise. Start-ups can build products around a model family while preserving the option to change the underlying checkpoint.
This increases contestability at the application layer. It can also accelerate diffusion. Techniques developed around one model, such as quantisation profiles, serving optimisations or evaluation harnesses, can spread through an ecosystem rather than remain entirely inside one provider.
Yet lower entry costs do not guarantee durable competition. If many applications use similar models and interfaces, distribution, proprietary data and workflow access become more important. A company that reaches customers through an existing enterprise platform may retain an advantage even when competitors can obtain comparable weights. The competitive bottleneck moves rather than vanishes.
Bargaining power becomes more credible
The option to run a model elsewhere can improve an enterprise’s negotiating position with hosted providers. It creates a reference price, a continuity option and a response to sudden changes in rate limits, product strategy or commercial terms.
The word “option” matters. Bargaining power is strongest when the alternative can actually be exercised. An organisation that has never run its evaluation suite against another model, does not control its prompts or tool definitions, and lacks a deployment path has little more than a presentation slide. The credible alternative is built through technical preparation.
Procurement should therefore distinguish contractual portability from operational portability. Contractual portability asks whether the organisation has rights to take its artefacts elsewhere. Operational portability asks whether it can do so within an acceptable time, cost and risk envelope. Both are necessary for the market pressure promised by open models to materialise.
Ecosystems can compound advantage
Open-weight model families can attract tool builders, fine-tuners, hosting providers and researchers. That ecosystem improves accessibility and creates feedback. The more deployment options and compatible artefacts exist, the easier it becomes for another organisation to adopt the model.
This dynamic can distribute innovation while strengthening a particular family as a de facto standard. A widely used tokenizer, adapter ecosystem or inference format can create its own switching costs. Openness does not prevent network effects. It changes who can participate in producing them and where control is exercised.
The practical question is not whether an ecosystem is open in the abstract, but whether its interfaces, licences and artefacts let an enterprise leave without discarding its investment. A broad community is valuable. A rehearsed exit remains necessary.
Upstream concentration can intensify
More downloadable models can mean more demand for accelerators, cloud capacity and optimised serving. Those markets have different economics from software distribution. They require large capital commitments, supply-chain access and energy. The UK Competition and Markets Authority has highlighted risks around access to key inputs, powerful partnerships and the ability of firms to shape routes to market.
Open weights can therefore produce a paradox: more choice at the model layer and continued concentration in the resources required to run those models at scale. A cloud provider can support many competing model families and still capture value from their deployment. A semiconductor provider can benefit regardless of which model wins.
For enterprise strategy, this means that supplier concentration must be assessed across the stack. Replacing a model provider while keeping the same cloud, accelerator, identity plane and observability tools may reduce one dependency while leaving the critical operating dependency untouched.
Closed providers do not stand still
It would be a mistake to treat open models as a force acting on a static proprietary market. Closed providers can respond with lower prices, smaller models, private deployment options, stronger tools, contractual protections and faster capability improvements. Integrated services may remain attractive precisely because they absorb operational complexity.
Closed systems can also differentiate in areas that weight releases do not automatically reproduce: multimodal interaction, long-running tool use, managed safety controls, support, indemnities, global capacity and a coherent developer experience. For many workloads, those complements can matter more than access to the parameters.
The competitive pressure from open models is therefore not a prediction that proprietary systems disappear. It is a constraint on how they price, package and justify their services. It makes the basis of competition broader.
The sovereignty paradox
Open weights can support national and organisational sovereignty. They can enable local-language adaptation, public-sector research, domestic deployment and continuity if access to a foreign API is constrained. They can also make it easier to inspect and modify a system for local needs.
But sovereignty is not a file location.
A country or company may host weights locally while depending on foreign accelerators, cloud orchestration, energy supply, specialist talent and upstream software. Infrastructure concentration can coexist with downstream openness. The OECD’s analysis of AI infrastructure competition is a reminder that chips, data centres and cloud capacity remain strategic bottlenecks.
A credible sovereignty plan therefore separates three goals: access to the model, operational autonomy, and the capacity to improve or replace the system. Open weights make the first easier. They contribute to the second. They do not guarantee the third.
The same logic applies to enterprise resilience. A locally deployed model can reduce dependence on one API while increasing dependence on one GPU supplier or a small group of engineers. Resilience improves only when dependencies are mapped, alternatives are tested and skills are sustained.
Run a portfolio, not a referendum
The open-versus-closed debate encourages organisations to make a philosophical choice where an engineering and business decision is required.
A better strategy is to manage a portfolio by workload. Closed frontier systems may be appropriate where top capability, integrated tools and operational simplicity justify the premium. Managed open-weight models may offer useful choice without forcing the enterprise to operate the full stack. Self-hosted or fully open systems may be preferable where control, auditability, adaptation, data boundaries or continuity dominate.
For each workload, ask ten questions:
- Quality: What task quality is required, and what failure modes are unacceptable?
- Data: What sensitivity, residency, retention and audit constraints apply?
- Performance: What latency, throughput, context and availability profile is needed?
- Rights: What does the exact model and checkpoint licence permit?
- Economics: Can dedicated infrastructure be kept sufficiently utilised?
- Capability: Can the organisation serve, secure, evaluate, patch and support the model?
- Adaptation: Is fine-tuning, quantisation or specialised inference genuinely required?
- Switching: Which application, runtime and platform dependencies would make replacement difficult?
- Governance: What legal role, risk classification and control evidence apply in each jurisdiction?
- Exit: What event triggers a move, such as a quality regression, cost crossover, licence change, vulnerability or better alternative?
The answers should produce an explicit deployment mode, not a generic preference. They should also be revisited. Model quality, pricing, licences, hardware and regulation change too quickly for a one-off selection to remain optimal.
Consider a document-analysis workflow in a regulated institution. The work may involve extracting terms, classifying clauses and drafting a review note, with a human accountable for the final decision. A hosted frontier model might deliver the best initial accuracy and fastest time to value. A managed open-weight model could provide a stronger residency posture without requiring the bank to run accelerators. A self-hosted model might become attractive once volumes are predictable, the evaluation suite is mature and the platform team can support the service.
The choice should not be made once for the whole workflow. Clause extraction may tolerate a smaller, cheaper model with deterministic validation. Complex exception analysis may justify a stronger hosted model. Sensitive documents may require a different boundary from public material. The portfolio can reflect those differences, provided that permissions, audit trails and fallbacks remain coherent.
This example also shows why model-only benchmarks are insufficient. The enterprise needs to test extraction accuracy by document type, the rate of unsupported conclusions, response consistency, latency at peak volume, the behaviour of validation rules, and the operational response when a model version changes. A system that performs slightly worse on a general benchmark can be the better production choice if it is more controllable on the actual task.
Common evaluation and routing can make the portfolio practical. An application can present a stable interface while different models serve different workloads or provide fallback. That design should not be romanticised: routing adds complexity, and weak evaluation can merely automate inconsistent choices. The point is to preserve justified options without creating uncontrolled variety.
Portfolio management also needs clear decision rights. A central AI platform team can maintain approved runtimes, identity controls, observability and common evaluations. Product teams can own workload requirements, domain tests and user outcomes. Legal, security, risk and model-governance functions can define evidence thresholds and escalation paths. Procurement can keep licence, pricing and exit terms current. Without this division of responsibility, model choice either becomes a slow central bottleneck or fragments into local experiments that nobody can support.
Version discipline is equally important. Every material decision should identify the model checkpoint, runtime configuration, prompt and tool versions, evaluation result and approval state. A change in weights can alter behaviour even when the application code does not move. An apparently minor switch between hosted and self-hosted variants can change logging, content filtering, data handling and incident responsibility. Treating the model as a versioned production dependency makes openness usable without pretending that interchangeability is free.
Finally, preserve a deterministic path for high-consequence actions. A model can classify, summarise or propose, while explicit rules, permissions and human approvals control what is executed. Open weights do not make autonomous operation inherently safer, and proprietary safeguards do not remove the need for application-level controls. The deployment mode changes where controls sit. It does not remove the obligation to design them.
Open models have made this portfolio strategy more credible. They have weakened the assumption that every capable AI system must be rented from one closed provider. Yet they have not removed the economics, engineering or governance required to turn a model into a dependable enterprise capability.
That is the real competitive shift. The model is becoming one component in a contest over the complete system. The organisations that benefit will not be those that declare allegiance to openness. They will be those that know which control matters, can pay the operational cost of exercising it, and can change models without losing the discipline around them.
Part 2 of this series will examine the economics more closely: the cost crossover among APIs, managed open models and self-hosted inference. Part 3 will turn to governance and the production operating model required to make a multi-model strategy safe.



Leave a Reply